Part 3 of 6
From a sheet of paper to a searchable archive
A pile of letters, a sticker and one button. How paper becomes an archive that files itself, and why I can still find the original in seconds.


You probably know the pile. Some people keep it on the desk, others in a drawer or a box marked “to file”. Letters from the insurance company, the annual utility bill, something from the tax office, and somewhere in there the invoice for the washing machine. And the one sheet you actually need is always at the very bottom.
An invoice like the washing machine one I pull up at the hardware store in part 2 never makes it onto a pile at my place. It arrives as a letter, gets a sticker, I press a button, and after that I don’t have to do anything. In the end the document has a title, a sender and tags, and the paper sits in a binder I can pull it out of in seconds.
A quick reminder of where we are. Part 1 showed my homelab as a house where every service has a flat of its own, a virtual machine or VM. Part 2 was the way in. Now, for the first time, we look inside a single flat. Living there is Paperless-ngx, a program that archives scanned documents and makes them searchable. Its VM is called paperless-01.
Before we follow the letter step by step, here’s the whole route. The left column happens at my desk, with the sticker, the scanner, a small computer next to it and the binder for the paper. The right column runs in the homelab without me, from a network folder through Paperless to a notification on my phone. I’ll explain the names in the boxes as we go.
Let’s start with step 1, the paper.
A number on every letter
A digital archive answers the question of what a letter says. Sometimes, though, I need the original, for a government office, say, or for that warranty claim. That’s what the ASN is for, the archive serial number. It’s a running number that’s stuck on the paper and stored with the document in Paperless.
The paper is filed by that number and nothing else, not by topic. New letters simply go in at the back of the binder, so filing takes no decisions at all. When I need an original, I look it up in Paperless, read off the ASN and flip to exactly that number in the binder. Sorting by sender, year and topic is the archive’s job. The binder only has to count.
Right now Paperless holds 768 documents, 666 of them with an ASN, the highest being 971. Gaps don’t matter. The binder stays in ascending order, and I just flip past a missing number.
The stickers
The number has to get onto the paper somehow, in a form both a person and a machine can read. The labels come from a small open-source tool of mine, ASN Label Maker. It builds a print-ready PDF with one label per page, 30 × 15 mm. On the left sits a QR code, one of those square patterns any phone camera can read, containing ASN00001. On the right are “ASN” and the five-digit number for human eyes.
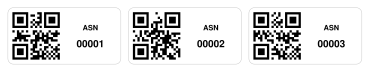
Why a QR code rather than a classic barcode? A QR code still reads well at 15 mm high and is recognised at any angle, even when the sticker went on crooked. A commit with the fitting name “improve QR code recognition for Paperless” also removed the white border from the code image. Since then the code fills almost the full label height, and Paperless reads it more reliably.
The second trick is about the roll. On a label roll, the last label printed ends up on the outside, so unrolling it would start with the highest number. With --reverse the script prints backwards, and the roll starts at 00001:
uv run python asn_labels.py 1 100 --reverse -o asn_labels.pdf
If you don’t want to install anything, a Colab notebook runs the script right in your browser and lets you download the PDF.
A button on the scanner
Sticker on, letter in the feeder. The scanner is a Fujitsu fi-6130Z, and next to it sits a Raspberry Pi, a small computer the size of a credit card. The Pi runs docscanner, a small Python program of mine that waits in the background for something to happen. A program like that is called a daemon. Once a second it asks SANE, the Linux scanner interface, whether anyone has pressed the scan button.
The ready-made tool scanbd could have done that too, but it needs several programs working together. This way everything lives in a single Python project that one command (uv sync) sets up again.
When I press the button, the Pi scans every page in the feeder on both sides at 600 dpi, one image per page. While the scanner is still running, each finished page is cleaned up in parallel. It’s straightened, its contrast is adjusted, and near-white paper grey becomes pure white. Then a tool called img2pdf merges the pages into a PDF named Scan_<date>_<time>.pdf.
The inbox folder
Now the PDF has to get from the Pi to Paperless. In between sits an inbox folder, a network folder that several computers can use at once, like a shared letterbox. It lives on my file server running TrueNAS, which is a NAS, a computer whose main job is providing storage on the home network. The Pi and paperless-01 both attach the folder, using NFS, the usual language for network folders on Linux.
The scan doesn’t go straight into the letterbox, though. It first lands in a queue on the Pi, and only then does docscanner move it into the inbox folder. If the network folder isn’t there at that moment, the file stays put and docscanner tries again every five minutes. So a scan isn’t lost just because the NAS is rebooting.
The folder is also attached “soft”. With the default, “hard”, a computer may wait forever for a network folder that has vanished. That once locked up the Pi so badly that remote login still worked but no command ever returned. Now an outage produces an error instead of a frozen system.
On the other side, Paperless checks the letterbox. Normally it learns about new files through a notification from the Linux kernel called inotify. Over NFS that doesn’t arrive reliably, so Paperless looks for itself every 15 seconds. It leaves half-written files ending in .part or .tmp alone. Everything else it takes in and deletes from the inbox, which Paperless calls “consuming”.
If you’ve read part 2, you know this spot already. TrueNAS isn’t part of the encrypted NetBird network yet, so the leg from the Pi via the NAS to Paperless crosses the home network unencrypted. Bringing TrueNAS into NetBird is the next step.
Inside Paperless
The scan is in Paperless now, and four things happen in turn. Two terms first. OCR means optical character recognition, turning a picture of text into real, searchable text; Paperless uses a program called Tesseract for it. And a webhook is a kind of doorbell between programs. When something happens, one program rings the other and tells it so.
| Step in Paperless | What happens |
|---|---|
| Barcode | Finds a QR code starting with ASN and stores the number as the document’s ASN |
| OCR | Tesseract recognises the text, pages are rotated upright, the result is a PDF/A, a PDF meant for archiving, with a text layer |
| Storage | The file is stored by correspondent, year and title |
| Workflow | “Document added” rings n8n via webhook and passes on the document ID |
The doorbell in the last step goes to the next neighbour in the house.
Who reads the letter?
The text is recognised, but the document is still called Scan_20261015_145321 and carries only the “Eingang” (inbox) tag. The rest is done by n8n, an automation tool where you plug workflows together from building blocks, a bit like shortcuts on a phone. It lives in the VM n8n-01. Each of these automations is called a workflow, and five of them make up my chain “Paperless 00–04”.
The one actually reading the letter is a language model, a program that has learned from huge amounts of text to understand and write text, like the one behind ChatGPT. Mine is Qwen3-30B-A3B. It runs with a program called llama.cpp on the integrated graphics of my workstation, not in the cloud, so the letter never leaves the house. The workflows also log only metadata such as the document ID and character count, never the content.
The picture shows the chain. Paperless rings at the top, in the middle workflow 00 calls the other four one after another, and at the bottom are the language model and the final notification.
The model answers in JSON, a text format laid out like a filled-in form with fixed fields. The table shows what each of the four workflows does. In Paperless, the correspondent is the sender.
| Workflow | What it does | Who decides |
|---|---|---|
| 01 OCR to JSON | Pulls sender, recipient, date, subject, amounts, reference numbers and a summary out of the recognised text and stores them as JSON in a custom field | language model |
| 02 Correspondent | Matches the sender to a known correspondent, otherwise “Unbekannt” (unknown) | fixed rules first, then the model |
| 03 Tags | Sets the person from the recipient and one to four topic tags | person by rule, topics by model |
| 04 Finish | Title from the subject, date if it is plausible; inbox tag off, “ai-processed” on | rules only |
The model may only choose
Handing my filing over to a language model with no strings attached felt too risky. So the most important rule of the chain is a simple one. Wherever there’s a list, the model may only pick from that list. llama.cpp can tie its answer to a JSON schema, a form template that fixes which fields and which values are allowed. For the tags it looks like this (shortened):
{"tags": {"type": "array", "minItems": 1, "maxItems": 4,
          "items": {"enum": ["<tag 1>", "<tag 2>", "…", "Unsortiert"]}}}
The list is fetched fresh from Paperless on every run. So the model can’t create a second correspondent with a slightly different spelling, and it can’t invent a new tag. If nothing fits, the document ends up as “Unsortiert” (unsorted) or “Unbekannt”, and I see it.
Where a simple rule will do, the chain doesn’t ask the model at all. Workflow 02 recognises frequent senders by fixed rules or their exact name, and only when that’s ambiguous does the model decide. That’s faster, and where a rule applies, it’s never wrong.
At the end, workflow 00 sends a single notification to my phone through ntfy, a self-hosted push service, with title, correspondent, document type and a link. It used to come straight from Paperless on “document updated”. Since every step of the chain updates the document, I got four notifications per letter, the first ones without a sender yet.
Keeping the model in the background wasn’t how things started, by the way.
From practice: Paperless has AI suggestions of its own, and at first they were switched on. Every document I opened sent a request to the language model, which took more than two minutes for long letters. llama.cpp had two slots for requests at the same time, and both were permanently busy. The browser gave up on waiting requests and, when I clicked on, on saving as well, with the message “Status 0”. I switched the built-in suggestions off. Since then the model only works through n8n in the background, where nobody is waiting for it.
Two consumers, one inbox
There was one thing about the inbox folder I only understood after the move, and the hard way.
From practice: On 29 October I found that the old Paperless installation from before the move was still running on my workstation. Its restart policy brought it back after every boot, the nightly backup only paused it briefly, and it had the same network folder attached as its inbox as
paperless-01. Whoever looks first takes the file. On 17 October the old copy had picked up a scan from the 15th, which was therefore missing from the new archive. I took the original out of the old installation and put it into the inbox ofpaperless-01, first as a hidden file, then renamed, so Paperless couldn’t grab a half-written file. The chain processed it with all five workflows, and the old copies are now stopped and no longer start on their own.
The picture shows the race. On the left, docscanner drops the scan into the inbox folder in the middle; on the right, both Paperless installations check it, and whoever gets there first takes it.
Since then I know that “switched off after the move” only means something once the restart policy is off too.
Back at the hardware store
So when I’m at the service desk again, I find the washing machine invoice through the search in Paperless, with a title and a sender that a language model picked from a list I gave it. If the shop wants to see the original after all, the ASN is right there on the document. At home I reach for the binder, flip to that number and have the sheet in my hand. There’s no room for a pile anywhere in this.
If I boil down what makes it work, it’s two simple ideas. Paper is filed by number, and the archive does the sorting. And everything slow happens in the background, from the queue on the Pi to the chain in n8n, which reports back with exactly one notification at the end.
paperless-01 is just one VM among many, and I didn’t click any of them together by hand. How does a text file become a running VM with a finished service? That’s part 4.